From Noisy Text to Real-World Applications of LLMs
The WNUT workshop on language by people. We focus on language as it occurs in the real world, from noisy text to real-world applications of LLMs.
Invited Talks
-
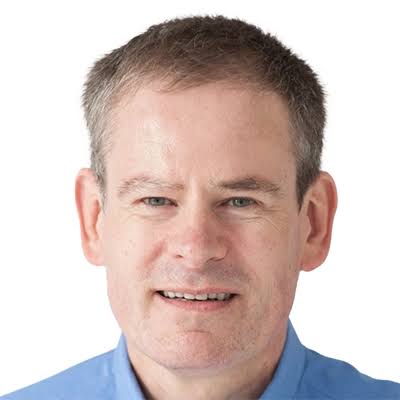
Language Identification in the (Pretraining) Data Processing Pipeline – State of the Art and Open Problems
Hinrich Schütze · Professor, University of Munich
Abstract to be announced.
Speaker bio
Hinrich Schütze is Professor for Computational Linguistics and co-director of the Center for Information and Language Processing at the University of Munich (LMU Munich). He received his PhD from Stanford in 1995 for his early research on embeddings (ACL Test-of-Time Paper Award). He then worked on natural language processing and information retrieval technology at Xerox PARC, at several Silicon Valley startups and at Google 1995-2004 and 2008/9. Hinrich is a coauthor of Foundations of Statistical Natural Language Processing (with Chris Manning) and Introduction to Information Retrieval (with Chris Manning and Prabhakar Raghavan). He was awarded a European Research Council Advanced Grant in 2017. Hinrich served as president of the Association for Computational Linguistics in 2020. He is a member of Academia Europaea and a fellow of ACL, ELLIS, ELIZA and HessianAI.
-
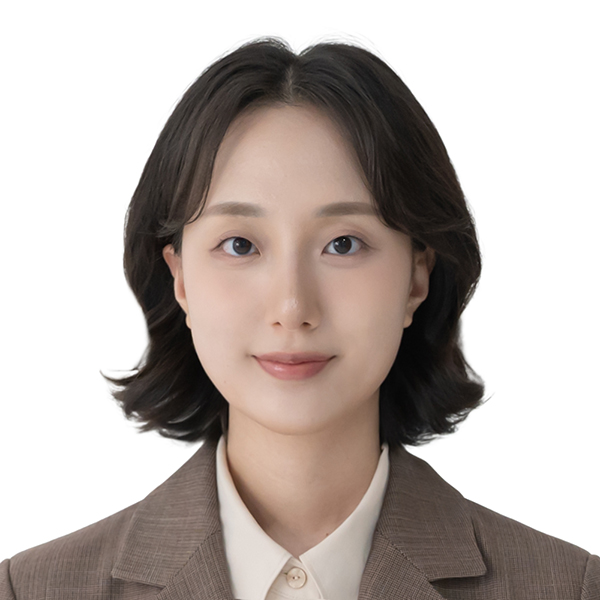
Enhancing Multilingual LLMs with Code-Switching
Haneul Yoo · Assistant Professor/Faculty Fellow, New York University
Despite recent advances, large language models (LLMs) exhibit uneven performance across languages and often struggle with code-switching—the natural alternation between multiple languages. While code-switching is a common and meaningful mode of human communication, LLMs remain brittle to code-switching inputs, treating them as noise. This talk reframes code-switching as a valuable linguistic signal, exploring how it can be leveraged across the LLM lifecycle, from evaluation, to training, to inference. I will begin with output language alignment (OLA), highlighting systematic failures to respond in the expected language in code-switching contexts. I will also introduce code-switching red-teaming (CSRT), which reveals vulnerabilities in safety and multilingual understanding. I will then present code-switching curriculum learning (CSCL), a data-efficient approach to cross-lingual transfer inspired by human second-language learning. Finally, I will introduce code-switching in-context learning (CSICL), which uses gradual transitions from a target language to English to improve multilingual generalization without additional training.
Speaker bio
Haneul Yoo is an Assistant Professor/Faculty Fellow in the Department of Computer Science, Courant Institute School of Mathematics, Computing, and Data Science at New York University. She is also a Research Fellow with the Social Innovation and Special Projects Team in the Division of Policy, Evaluation and Training, Department of Peace Operations at the United Nations. She received her PhD from the School of Computing at KAIST. With a background in machine learning (ML) and natural language processing (NLP), she has worked on (1) developing language models and methods to improve generalization across languages, (2) designing resources and evaluation frameworks for underrepresented languages and cultures, and (3) applying AI in high-stakes, real-world domains for social good. She has published papers in major NLP conferences, including ACL, EMNLP, and NAACL, and has been named a Rising Star at KAIST exploreCSR supported by Google. She has served as a Social Chair at NeurIPS 2026 and co-organized the Multilingual and Equitable Language Technologies (MELT) workshop at COLM 2025, the Women in Machine Learning (WiML) symposium at ICML 2026, and the Generative AI for the World (GenAI4World) workshop at COLM 2026.
-
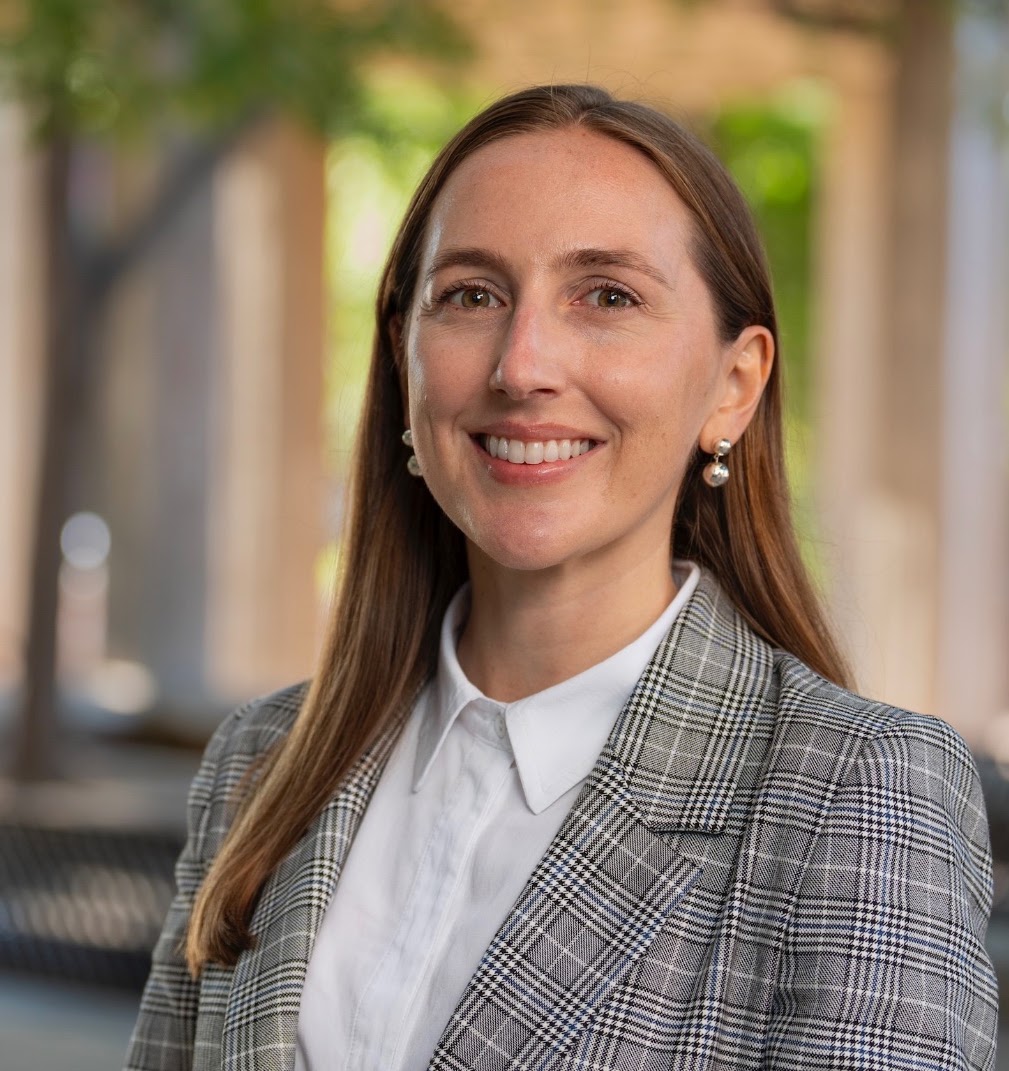
When Noise Is the Point: What Humanistic Tasks Reveal About Our Data Pipelines
Maria Antoniak · Assistant Professor, University of Colorado Boulder
In computational studies of humanistic tasks such as storytelling and poetry, we often encounter datasets whose features frustrate standard NLP pipelines. In this talk, I'll draw on three settings where my collaborators and I have run into this friction. First, I'll discuss user–chatbot conversations like WildChat, where creative requests are long, detailed, and frequently revised, making these logs a rich but also complicated view of how people write with chatbots. Second, I'll describe our development of a fine-grained narrative annotation scheme for very large-scale, heterogeneous web text in pretraining data, where operationalizing a humanities concept is complicated by data diversity. Third, I'll turn to poetry, where the linearization systems used to build training corpora routinely flatten or delete formatting that poets use deliberately. Across these cases, I'll argue that what counts as noise depends on who is reading and for what purpose, and that taking humanistic perspectives seriously can help us build data practices, annotation schemes, and evaluations that better reflect how people actually use language.
Speaker bio
Maria Antoniak is an Assistant Professor of Computer Science at the University of Colorado Boulder where she is also affiliated with the Department of Information Science and a member of the Boulder NLP Group. Previously, she was a Young Investigator at the Allen Institute for AI and a postdoc at the Pioneer Centre for AI at the University of Copenhagen. She completed her PhD in Information Science at Cornell University and her master’s degree in Computational Linguistics at the University of Washington. She has also spent time at places like ETH Zürich, Microsoft Research FATE, Twitter Cortex, and Facebook Core Data Science. Her research is in natural language processing and cultural analytics.
Workshop Schedule
| Date | Event |
|---|---|
| July 25th | Submission Deadline (anytime on earth; dual-submission allowed) |
| August 22nd | ARR Commitment Date |
| August 25th | Acceptance Notification |
| September 6th | Camera-Ready Deadline |
| September 11th | EMNLP 2026 Findings Deadline |
| October 28th | Workshop Day |
Wednesday, October 28, 2026
- 09:00 – 09:30Welcome
- 09:30 – 10:30Keynote 1: Hinrich Schütze Language Identification in the (Pretraining) Data Processing PipelineRoom G15-16
- 10:30 – 11:00Coffee Break & Networking
- 11:00 – 12:30Oral Presentations
- 12:30 – 14:00Lunch
- 14:00 – 15:00
- 15:00 – 16:00Poster Session
- 15:30 – 16:00Coffee Break & Networking
- 16:00 – 17:00Keynote 3: Maria Antoniak When Noise Is the Point: What Humanistic Tasks Reveal About Our Data PipelinesRoom G15-16
- 17:00 – 17:30Closing & Next Steps
26 accepted papers, listed alphabetically by title.
-
A Precision-First Whitespace Restoration Pipeline for Noisy Urdu Tafseer Text
-
Are More Emotion Theories Better? Joint Prompting Improves Emotion Categorization Robustness
-
Beyond Clean Text: Evaluating Encoder and Decoder Robustness for Bangla Event Detection in Noisy Text
-
CrisisKD: Five-Stage Knowledge Distillation for Aspect-Level Sentiment and Emotion Analysis in Crisis Discourse
-
Discourse-Structural Noise in LLM-Generated Explanations
-
Do LLMs Give Consistent Opinions? Evaluating Response Reliability Under Varying Likert-Scale Formulations in Survey-Style MCQA
-
Evaluating Token Probabilities as Confidence Estimators in Human Behavior Simulations: A Case Study in Luxembourgish Next Like Prediction
-
From Errors to Precision: A Taxonomy-Guided Approach for LLM Flood Cause Extraction
-
GeNERscore: Semantic Alignment Metrics for Generative Named Entity Recognition
-
How Noisy is Automatic Annotation? Characterizing Label Noise from Generative Models in Multi-Dimensional Spanish Subjectivity Annotation
-
Increasing the Robustness of the Fine-tuned Multilingual Machine-Generated Text Detectors
-
LLMs are Easily Startled: Fragility Testing with Lookalike Character Noise
-
Multi-author style detection with stylistic embeddings
-
NERQual: Evaluating the Robustness of Named Entity Recognition Models to Data Quality Issues
-
Not All Duplicates Are Coordination: Generic vs. Non-Generic Duplicate Campaigns in Information Operations
-
Personalized Emotion Analysis via Prompting Large Language Models with Writer Information
-
Predicting Steering Vectors and Adapter Weights for Few-Shot Author-Style Transfer
-
QueryDiagramEval: Evaluating and Benchmarking LLM Diagram Generation under Noisy Conditions
-
Robust Dual-Signal Fusion: Hybrid Neuro-Symbolic Gating with Compressed Chain-of-Thought Refinement for Irony Detection in Social Media Texts
-
RSPC: A Benchmark for Modeling Stress and Psychiatric Conditions in Digitally Mediated Relationships using Psychiatrist Annotations
-
Spoiler Court: Interpretable Spoiler Detection via Adversarial Multi-Agent LLM Judgement
-
The Curse of Multilinguality in Lexical Normalization
-
Topic Matching in the Wild: Benchmark and Lessons from Real-World ASR Transcripts
-
TurEngMix: A Text Corpus and Benchmark for Turkish-English Code-Mixed Language Identification and Named Entity Recognition
-
When Noise Fabricates Bias: The Fragility of LLM-as-a-Judge Bias Measurement under Noisy Text
-
Where Does Noise Robustness Live? Evidence from Ablation, Role Swaps, and Cross-Lingual Transfer in Code-Mixed Banking NLU
We seek submissions of long and short papers on original and unpublished work (same page limit as the EMNLP 2026 main conference). All accepted submissions will be presented as talks and/or posters at the workshop, following the EMNLP 2026 main conference.
We welcome submissions addressing (but not limited to) the following areas:
Classical NLP Tasks on Noisy Text
- NLP of noisy text, e.g., POS and NER tagging, parsing
- Text normalization and error correction
- Paraphrase identification and semantic similarity of short text or noisy text
- Extracting user demographics, profiles, and major life events
- Machine translation and multilingual NLP over noisy text
- Information extraction from noisy text and event extraction
- Colloquial language, e.g., idiom detection
- Domain adaptation to user-generated text
- Detecting rumors, contradictory information, sarcasm, and humor on social media
- Sentiment analysis
- Temporal aspects of user-generated content (resolving time expressions, concept drift, etc.)
- Representing and mining language variation in user-generated content
LLMs and Noisy Text
- Robustness of LLMs to noisy, ungrammatical, or informal input
- Training and fine-tuning of LLMs on user-generated text
- Evaluation methodologies for LLMs on noisy text
- Domain adaptation of LLMs to specific user-generated text domains
- LLM-generated noisy text: detection, characteristics, and implications
- Instruction-following in LLMs when faced with noisy or ambiguous prompts
- Retrieval-augmented generation (RAG) with noisy documents
Real-World LLM Applications
- LLM performance on text from social media, forums, and messaging platforms
- Handling code-switching, slang, and emerging language in LLMs
- LLMs for content moderation and safety in user-generated contexts
- Multilingual and cross-lingual LLM applications on informal text
- LLMs for assisting language learners and processing learner text
- Bias, fairness, and representation in LLMs trained on user-generated text
We particularly encourage submissions that address multilingual challenges, low-resource languages, cross-platform variations, and the unique characteristics of user-generated text across different communities.
Submissions should conform to the ACL style guidelines. Long and short paper submissions must be anonymized. Please submit your papers via:
Submit via OpenReview Commit via ARR
Double Submission Policy: Papers that have been or will be submitted to other meetings or publications must indicate at submission time. Authors of a paper accepted for presentation must notify the workshop organizers by the camera-ready deadline as to whether the paper will be presented or withdrawn.
EMNLP 2026 Findings: If you would like to present your EMNLP findings paper at WNUT, please fill out the following form by TBA.
Shared Task
This year, we host MultiLexNorm2026: a shared task on multi-lingual lexical normalization with a focus on non Indo-european languages. After the success of our first MultiLexNorm shared task held in 2021, we have extended our benchmark to more varied languages. More information about MultiLexNorm2026.
Organizers
Contact
JinYeong Bak jy.bak@skku.edu
Program Committee
We thank the W-NUT 2026 program committee members for their contributions to the review process. Members are listed alphabetically by first name.
-
Aditya Jain
-
Advitya Gemawat
-
Alba Pérez-Montero
-
Albina Sarymsakova
-
Alexander Mehler
-
Alistair Plum
-
Anay Abhijit Dombe
-
Ankit Bhattacharjee
-
Antonios Anastasopoulos
-
Ashfaq Ali Shafin
-
Avinash Goutham Aluguvelly
-
Bitan Majumder
-
Bogdan Savelyev
-
Bolei Ma
-
Chao Jiang
-
Claire Wang
-
Cooper Ballard
-
Danae Sanchez Villegas
-
Danilo Croce
-
Danni Liu
-
Diana Inkpen
-
Eduardo Blanco
-
Emily Allaway
-
Eshaan Jain
-
Fayeq Jeelani Syed
-
Federico Ruggeri
-
Gianmarco Pappacoda
-
Günter Neumann
-
Hari Kang
-
HyunJin Kim
-
Iñaki San Vicente
-
Ishan Jindal
-
Jaehyeok Lee
-
Jane Arleth dela Cruz
-
Julia Mendelsohn
-
Julina Maharjan
-
Khandaker Mamun Ahmed
-
Krityapriya Bhaumik
-
Linsey C. Yang
-
Lucy H. Lin
-
Manuel Montes
-
Manuel R. Ciosici
-
Maria Antoniak
-
Mariët Theune
-
Marko Haralovic
-
Markus J. Hofmann
-
Mike Zhang
-
Mirco Schönfeld
-
Monica Hegde
-
Muhammad Mubashir Hassan
-
Naoki Otani
-
Nathanael Chambers
-
Nelu D. Radpour
-
Nikola Ljubešić
-
Nils Schwager
-
Noor Mairukh Khan Arnob
-
Onat Dogan Akca
-
Phuong-Anh Nguyen-Le
-
Piyush Agarwal
-
Raghvi Baloni
-
Rajeel Ahmad Ansari
-
Rajveer Singh Pall
-
Richard Sproat
-
Ruslana Margova
-
Sai P Vallurupalli
-
Sai Tulasi Kolapudi
-
Saman Rahbar
-
Sangmin Song
-
Seongwoo Choi
-
Shreyash Rawat
-
Sivaraaman Balakrishnan
-
Souvik Das
-
Suhyeon Park
-
Tanmoy Mazumder
-
Tanvir Ahmed Sijan
-
Ted Zhang
-
Vincent Ng
-
Xiliang Zhu
-
Xinyu Li
-
Xuanjing Chen
-
Yangfeng Ji
-
Yashdeep Thorat
-
Yasuhide Miura
-
YeongJun Hwang
-
Yuval Pinter
-
Zihao Zheng